// DARK · Point-of-care fetal ultrasound
Diagonal-Anchored Repulsive Knowledge Distillation
for vision-language models under extreme compression
1Computer Vision Department, Mohamed bin Zayed University of AI (MBZUAI), Abu Dhabi, UAE · *Corresponding author
HC18 biometry validity, zero-shot (%)
0 → 100- HC18 validity
- 88.6%+5.1% over teacher
- Brain sub-plane F1
- 0.784+8.2pp over teacher
- iPhone 16 Pro latency
- 1.6 ms24× faster than teacher
- Visual parameters
- 11.4M26× fewer than teacher
// 01 Summary
Bringing fetal ultrasound AI to the point of care
Fetal ultrasound AI could transform prenatal care in low-resource settings, yet current foundation models exceed 300M visual parameters, precluding deployment on point-of-care devices. Standard knowledge distillation fails under such extreme capacity gaps (~26×), as compact students waste capacity mimicking architectural artifacts of oversized teachers.
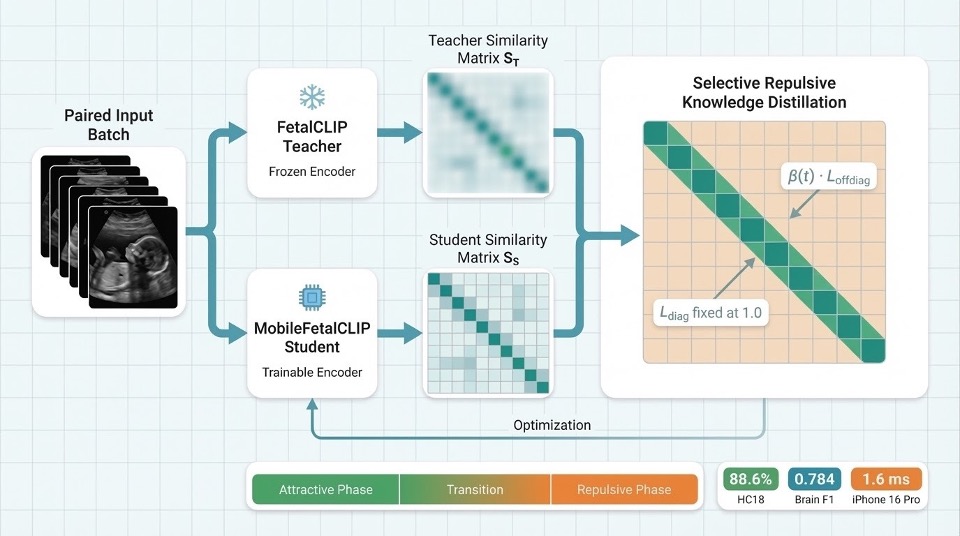
We introduce Diagonal-Anchored Repulsive Knowledge Distillation (DARK), which decomposes contrastive KD into diagonal and off-diagonal components: the diagonal term anchors matched-pair alignment throughout training, while the off-diagonal weight is annealed from positive to negative, repelling the student from the teacher's inter-class confusions and forcing discovery of architecturally native features.
Distilling FetalCLIP with DARK yields MobileFetalCLIP, whose 11.4M-parameter visual encoder surpasses the 304M-parameter FetalCLIP teacher encoder on zero-shot HC18 biometry validity (88.6% vs. 83.5%) and brain sub-plane F1 (0.784 vs. 0.702), while running at 1.6 ms on iPhone 16 Pro, enabling real-time assistive AI on handheld ultrasound devices.
Contributions
- DARK. An architecture-agnostic method that decomposes contrastive KD into diagonal (matched-pair) and off-diagonal (non-target) components. The diagonal term stays anchored while repulsion is applied only to the off-diagonal structure.
- MobileFetalCLIP. A mobile-scale vision-language model (75M total, 11.4M visual parameters) that surpasses the 427M FetalCLIP teacher on HC18 validity (+5.1pp) and brain sub-plane F1 (+8.2pp), while retaining 97–98% of linear probing performance.
- Mechanistic analysis. Embedding geometry, logit distributions and controlled ablations show that DARK produces structured decorrelation, with a silhouette score 40% higher than static KD.
// 02 The app
SonoSight: the model running on a phone
SonoSight is the mobile experience built on top of MobileFetalCLIP for real-time fetal ultrasound assistance. This short prototype demo shows the app flow, model-driven guidance, and the kind of handheld interaction the project is targeting.
- Runs the released MobileFetalCLIP model stack in a handheld workflow
- Shows the product direction beyond benchmark tables and paper figures
- Matches the point-of-care deployment story presented in the paper
// 03 Method
Learning what the teacher doesn't know
The problem. Standard KD forces a small student to strictly mimic a massive teacher (304M parameters). At a 26× capacity gap, the student wastes parameters learning the teacher's architectural artifacts (ViT-specific self-attention confusions) instead of discriminative medical features.
Our solution. During the repulsive phase, the off-diagonal loss weight β(t) becomes negative. Instead of copying the teacher's mistakes, the student is actively repelled from the teacher's confusion patterns, forcing discovery of native local-texture features. Training moves through three phases:
The student absorbs domain knowledge from the teacher's similarity structure.
The KD term contributes negligibly; the student is driven by the CLIP objective.
The gradient inverts: the student learns to separate classes differently from the teacher.
// 04 Results
Surpassing the teacher at 26× fewer parameters
We evaluate zero-shot on fetal ultrasound benchmarks against the FetalCLIP teacher, general-purpose vision-language models, and MobileFetalCLIP variants trained with other distillation objectives. DARK gives the best HC18 validity and brain sub-plane F1 of any model, including the teacher.
Table 1. Zero-shot comparison on fetal ultrasound benchmarks
| Model | Params | HC18 (%) | F1-5Plane | F1-3Brain | F1-all |
|---|---|---|---|---|---|
| Teacher | |||||
| TeacherFetalCLIP (ViT-L/14) | 427M | 83.5 | 0.973 | 0.702 | 0.871 |
| General VLMs (not fetal-specific) | |||||
| CLIP (ViT-L/14) | 427M | 11.0 | 0.308 | 0.206 | 0.270 |
| BiomedCLIP (ViT-B/16) | 150M | 24.0 | 0.603 | 0.236 | 0.466 |
| UniMed-CLIP (ViT-B/16) | 150M | 9.0 | 0.679 | 0.187 | 0.495 |
| MobileFetalCLIP variants (FastViT, 75M total) | |||||
| No KD (CLIP only) | 75M | 71.3 | 0.889 | 0.712 | 0.823 |
| Static Logit KD (CLIP-KD baseline) | 75M | 79.4 | 0.946 | 0.715 | 0.859 |
| Coupled Repulsive KD (r=−0.8) | 75M | 84.4 | 0.933 | 0.763 | 0.869 |
| OursDARK (β₀=2, r=−0.8) | 75M | 88.6 | 0.946 | 0.784 | 0.886 |
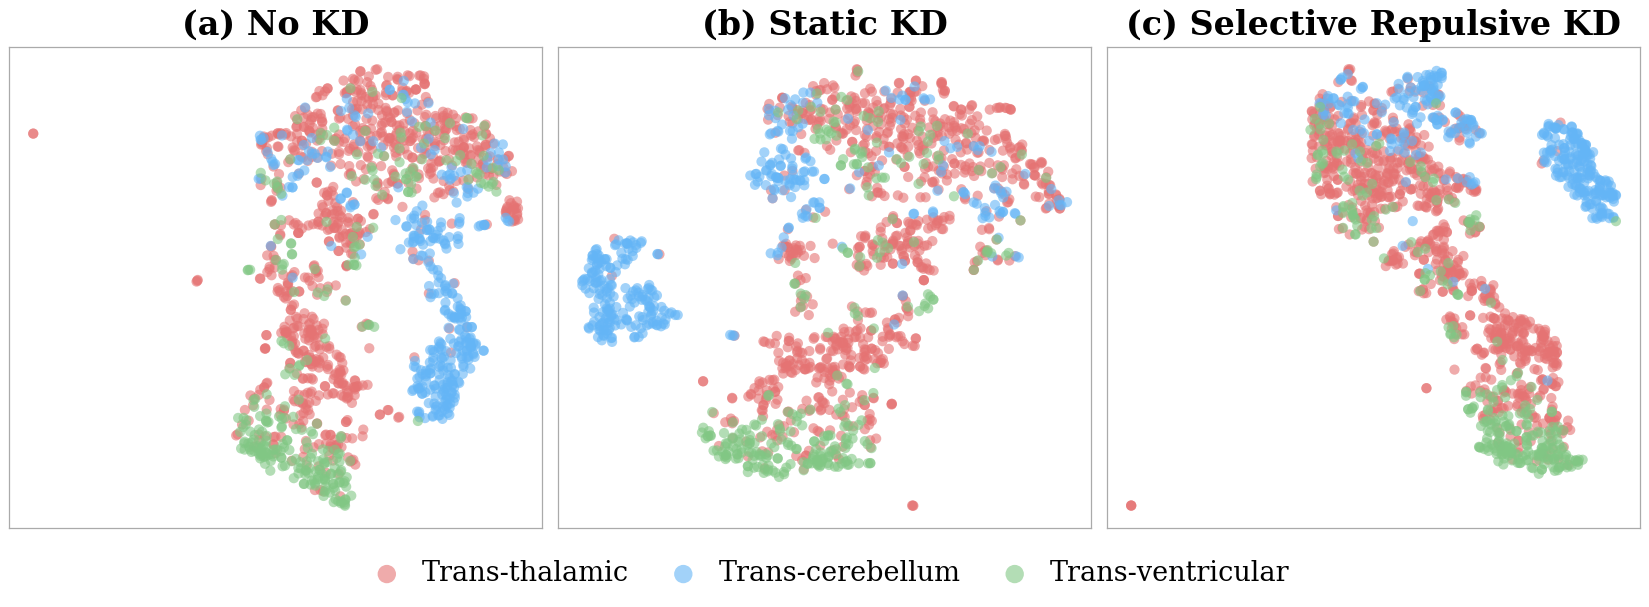
Table 2. Embedding geometry on Planes DB (5-plane, 8,187 images)
| Method | d_eff ↑ | Silhouette ↑ | Intra ↑ | Inter ↓ | Uniformity ↓ |
|---|---|---|---|---|---|
| Static KD (λ=1.0) | 8.0 | 0.375 | 0.712 | 0.445 | −1.662 |
| Confidence Penalty | 9.0 | 0.406 | 0.693 | 0.389 | −1.811 |
| Coupled r=−0.8 | 6.4 | 0.509 | 0.645 | 0.010 | −2.231 |
| OursDARK β₀=2 | 10.0 | 0.525 | 0.623 | 0.076 | −2.308 |
// 05 On-device speed
Real-time AI at the point of care
MobileFetalCLIP needs 32× fewer GMACs and 26× fewer parameters than the teacher, and runs 24× faster on an iPhone 16 Pro. At 1.6 ms per image it exceeds 600 frames per second, 10–20× faster than the 30–60 fps of diagnostic ultrasound. On an iPhone 14 the teacher runs out of memory, while MobileFetalCLIP runs in 3.8 ms.
Table 3. Inference efficiency
| Model | Params | GMACs | iPhone 14 | iPhone 16 Pro |
|---|---|---|---|---|
| FetalCLIP (teacher) | 304M | 49.4G | OOM | 37.6 ms |
| Static KD (baseline) | 11.4M | 1.5G | 3.8 ms | 1.6 ms |
| OursMobileFetalCLIP | 11.4M | 1.5G | 3.8 ms | 1.6 ms |
Table 4. Linear probing: frozen feature quality
| Model | 6-View F1 | Brain F1 | CHD AUROC |
|---|---|---|---|
| CLIP (ViT-L/14) | .867 | .634 | .679 |
| BiomedCLIP (ViT-B/16) | .856 | .582 | .643 |
| UniMed-CLIP (ViT-B/16) | .860 | .607 | .718 |
| FetalCLIP (ViT-L/14) | .947 | .820 | .787 |
| OursMobileFetalCLIP (FastViT) | .93098.2% | .79997.4% | .76997.7% |
MobileFetalCLIP retains 97–98% of the FetalCLIP teacher's linear probing performance at 26× fewer visual parameters (percentages in blue): frozen encoder + single linear layer, 5-fold × 5 seeds, 95% CI.
// 06 Citation
Cite this work
@article{saeed2026dark,
  title     = {DARK: Diagonal-Anchored Repulsive Knowledge Distillation
               for Vision-Language Models under Extreme Compression},
  author    = {Saeed, Numan and Hanif, Asif and Maani, Fadillah Adamsyah
               and Alasmawi, Hussain and Yaqub, Mohammad},
  journal   = {arXiv preprint arXiv:2603.05421},
  year      = {2026}
}